Copy text out of a chat interface and paste it somewhere strict — a CMS, a code review, a database field — and strange things appear. Extra spaces, weird line breaks, characters you cannot see. This is not model sloppiness; it is the reality of text that has been copied, reformatted, and passed through multiple editors.
The usual suspects
- Zero-width characters — invisible, but present in the byte stream, and capable of breaking validation or string comparison.
- Non-standard spaces — non-breaking spaces and other Unicode space characters that regex like
\smay or may not match. - Mixed line endings — CRLF and LF, which break diffs and patch tools.
- Over-collapsed whitespace — multiple spaces and blank lines that make output look unpolished in any fixed-width context.
A practical pipeline
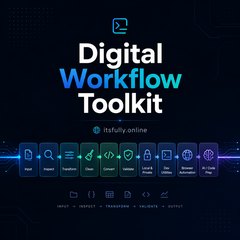
Cleaning is a pipeline of small, testable steps, and it is exactly the kind of work best done with single-purpose tools:
Going deeper on this theme: How to Remain Valuable When Intelligence Becomes Cheap — the scarce human, economic, and strategic advantages that stay valuable when AI does the cognitive work. A 224-page practical book, $3.84. Read it on Gumroad →
- Copy-Paste Cleanup for AI Outputs — a first pass for common copy-paste artifacts.
- Remove Invisible Characters — strips zero-width and other hidden characters.
- Whitespace & Line Cleanup — normalizes spacing and line endings.
Run them in order and the output is predictable: visible characters only, consistent whitespace, clean line endings.
Why bother
Text that looks fine on screen can fail silently in code: an invisible character in a slug, a non-breaking space in a comparison, a CRLF in a patch. Cleaning before shipping is cheap insurance — and it is one more job the browser can do locally, without sending your draft anywhere.